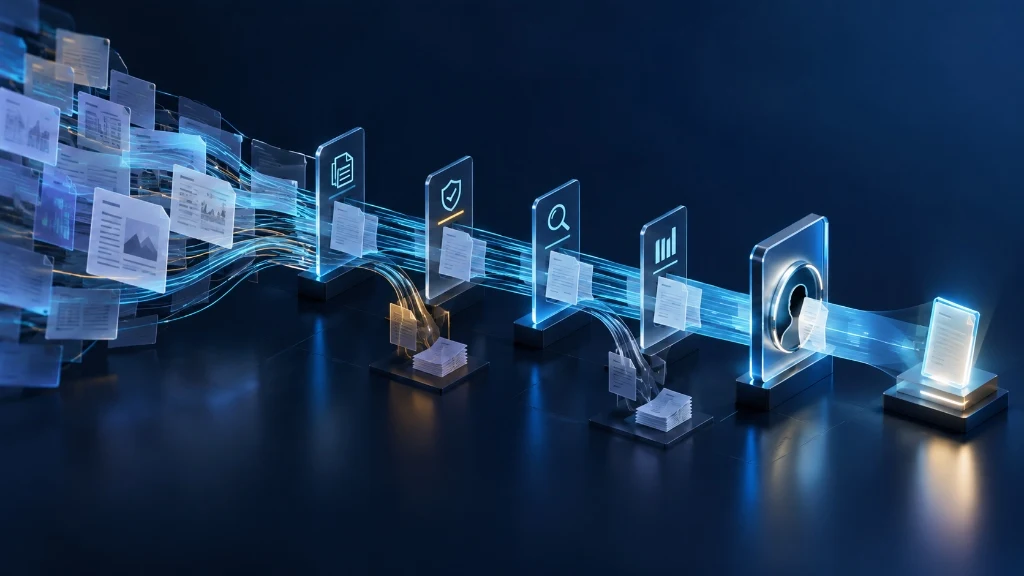
A suitable AI use case is one where artificial intelligence can materially improve a defined business process, suitable data exists or can be reliably obtained, the expected business benefit justifies implementation complexity, operational risks can be controlled, and the solution can be integrated into the real workflow.
SunSolv AI Opportunity Framework
A practical seven-dimension framework for evaluating whether a business challenge is suitable for AI.
A practical SunSolv framework to help organizations determine whether an operational challenge genuinely warrants an AI investment.
Problem
"Is there a specific, recurring bottleneck with high friction?"
Identify a concrete business friction point with clear operational boundaries rather than an abstract ambition to use machine intelligence.
- Can the bottleneck be defined in operational metrics (hours, error rates, turnaround)?
- Is the problem recurring frequently enough to warrant custom engineering?
Process
"How does the workflow operate today, and who is involved?"
Map the current end-to-end workflow, upstream inputs, downstream handoffs, and the exact roles of employees participating in the task.
- Where does information originate, and where does it need to go?
- What subjective interpretations do humans currently perform in the process?
Data
"Do suitable, high-quality historical and live datasets exist?"
Examine whether representative data is accessible, labeled or structured appropriately, compliant with privacy regulations, and available with proper access rights.
- Is historical data accessible without multi-month data-cleansing projects?
- Does the company have clear legal permission to process this information via models?
Value
"Does the expected benefit clearly justify implementation complexity?"
Compare tangible business returns (cost savings, capacity unlocking, faster turnaround, reduced error penalties) against ongoing compute, licensing, maintenance, and oversight overhead.
- Will this solution unlock capacity or directly reduce operating expense?
- Are ongoing infrastructure and token costs factored into ROI calculations?
Risk
"What is the blast radius when the model produces an incorrect output?"
Analyze failure modes, hallucinations, edge-case frequency, and regulatory or financial exposure when the model makes a mistake.
- What happens if the model is wrong 5% of the time? 1% of the time?
- Can failures be caught before affecting clients, transactions, or compliance audits?
Integration
"Can the solution connect into the existing operational environment?"
Assess how easily the capability connects with ERPs, CRMs, custom databases, and existing employee software via secure APIs and asynchronous messaging.
- Will employees need to toggle to another browser tab, or is it native in their tools?
- Are existing systems modern enough to receive real-time webhooks or API calls?
Measurement
"Are there baseline metrics established before implementation begins?"
Define objective success criteria, validation baselines, latency thresholds, and adoption benchmarks prior to engineering.
- What is the current human benchmark for turnaround time and accuracy?
- What threshold defines a successful pilot versus a failed experiment?
Why Organizations Often Start with the Wrong AI Question
Many organizations begin by asking what they can do with artificial intelligence rather than asking which operational bottlenecks are creating the highest friction in their business.
The surge of interest in artificial intelligence has led many technology and business leaders to begin projects with a tool-first mindset. Executives frequently ask: "Where can we implement generative AI?" or "How can we use language models in our business?"
While curiosity is understandable, starting with the technology almost always produces solutions in search of problems. Teams expend capital and engineering effort building proof-of-concepts that look impressive in demonstrations but fail to achieve organizational adoption because they do not address a critical operational pain point.
A sustainable AI initiative begins from the opposite direction. It starts by identifying business processes that are constrained by manual review, inconsistent interpretation, or unstructured information, and evaluates whether machine learning is the most practical and dependable remedy.
Start with the Business Problem, Not the AI Model
Technology selection should always follow a thorough definition of the commercial or operational friction point.
Before evaluating models, vector databases, or machine learning pipelines, leadership teams must articulate the exact problem they are attempting to solve. A well-defined business problem typically exhibits three characteristics:
First, it has a measurable impact on operations, such as delayed order processing, high customer wait times, repetitive manual data re-entry, or inconsistent compliance checking. Second, it is experienced repeatedly across regular business cycles. Third, current operations are bottlenecked either by employee hours or by cognitive fatigue during repetitive analytical tasks.
When you define the problem in business terms—such as "Our underwriting team spends 40 hours per week manually extracting balance sheet figures from scanned PDF audits"—the criteria for technology evaluation become concrete and objective.
Understand the Current Operational Workflow
An intelligent capability cannot be effectively deployed into a workflow that has not been mapped and understood.
Technology cannot fix an ambiguous or broken business process. Before introducing any intelligent tool, document the current workflow step by step: where data enters, who reviews it, what criteria govern decisions, where exceptions are escalated, and what downstream systems receive the final output.
Pay particular attention to the tacit knowledge that experienced employees apply. Often, manual workflows include unwritten rules, informal sanity checks, and domain context that are not captured in formal documentation.
Understanding these nuances allows you to identify where machine intelligence can assist humans, where conventional rules should remain intact, and where human discretion must be preserved.
Determine Whether Rules-Based Automation Is Enough
If a process can be reliably completed using deterministic if-then logic, rules-based automation is usually more cost-effective, faster, and more dependable than AI.
One of the most consequential decisions in any modernization effort is deciding whether a task actually requires artificial intelligence or whether conventional software automation is sufficient.
Conventional automation—such as API integrations, scheduled database jobs, schema validations, and deterministic business rules engines—excels when inputs are structured and expected outcomes follow strict logic. It can provide highly predictable behaviour when inputs and business rules are well defined, can operate with relatively low computational overhead and predictable execution characteristics, depending on the implementation, and is straightforward to audit.
AI may become appropriate when the task requires interpretation, classification, prediction, generation or handling meaningful variability that deterministic rules cannot address reliably. Applying a neural network or language model to a task that can be solved with a database query or regular expression often introduces unnecessary fragility, higher operational cost, and latency.
Practical Example: Processing Large Volumes of Semi-Structured Business Documents
Comparing manual processing, traditional rules-based automation, and AI-assisted extraction demonstrates how task variability dictates the appropriate technology choice.
Consider a mid-sized organization receiving thousands of supplier invoices, delivery notes, and purchase orders each month from hundreds of different vendors.
Under manual processing, staff open each document, locate total amounts, line items, and invoice dates, and manually type them into the ERP. This approach is highly flexible and catches bizarre anomalies, but it scales linearly with headcount, slows turnaround times during peak periods, and is vulnerable to keystroke errors.
Under traditional rules-based automation (such as zonal OCR), templates must be created for each vendor layout. If Vendor A changes their PDF format, moves the total box down two centimeters, or sends an unformatted scan, the template breaks completely, generating an exception queue that requires developer or administrative intervention.
Under an AI-assisted workflow, an intelligent document model extracts key-value pairs semantically regardless of layout shifts. It handles multi-page tables, rotated scans, and diverse naming conventions ("Total Due" vs "Balance Outstanding"). However, because model outputs are probabilistic, the system assigns a confidence score to each field. High-confidence extractions pass automatically into the ERP via rules-based validation, while low-confidence extractions are flagged for human review.
The most appropriate approach depends on variability and consequences. For uniform, standardized receipts from three suppliers, rules-based automation is superior. For diverse documents from hundreds of vendors, the hybrid AI-assisted model delivers significant capacity savings while managing risk.
Evaluate Data Availability and Quality
AI capabilities are constrained by the consistency, accessibility, and legal permissions of the data they consume.
Without accessible, representative data, machine learning initiatives stall. Assessing data readiness requires answering four practical questions:
1. Availability: Does the organization actually store the information needed, or is it trapped in disparate paper files, isolated local spreadsheets, or third-party proprietary systems?
2. Quality and Consistency: Are data fields clean, consistent, and standardized, or are there widespread discrepancies, missing values, and corrupted entries?
3. Volume and Diversity: Is there enough historical volume reflecting real-world edge cases, seasonality, and unusual exceptions to properly validate the system?
4. Governance and Rights: Does the organization possess the explicit contractual and regulatory right to feed this data to cloud models or internal inference engines?
If data preparation requires a multi-year restructuring of all enterprise databases, starting a complex AI project immediately will lead to frustration. In such scenarios, modernizing data pipelines is the necessary prerequisite.
Assess Expected Business Value and Implementation Complexity
A compelling AI use case must demonstrate clear operational returns that comfortably exceed both upfront engineering and recurring infrastructure costs.
Calculating the true cost of an AI deployment extends well beyond the initial software development contract. Ongoing expenses include API token costs, compute hosting, continuous monitoring for model drift, prompt engineering maintenance, and staff training.
Expected business value should be quantified across specific dimensions: reduction in processing cycle time, increased transactional capacity without proportional hiring, fewer downstream reconciliation penalties, or faster response times for customers.
If a proposed capability saves an employee 15 minutes per week but costs thousands of dollars monthly in infrastructure, review time, and model maintenance, the initiative lacks commercial justification. Prioritize use cases where the ratio of operational value to technical complexity is clearly favorable.
Understand the Cost of Incorrect AI Output
Every artificial intelligence model produces occasional errors; evaluating a use case requires understanding the real-world operational blast radius of those mistakes.
Unlike deterministic software which produces consistent results for given inputs, AI systems operate probabilistically. They will occasionally misclassify an input, extract an incorrect number, or hallucinate a plausible-sounding falsehood.
The feasibility of an AI use case depends heavily on the cost of an error. In low-stakes applications—such as drafting an initial summary of meeting notes or recommending related articles—an occasional minor error is easily corrected by the reader with minimal consequence.
In high-stakes processes—such as automated loan approval, clinical prescription checking, safety-critical equipment control, or automated legal contract execution—a single incorrect output can lead to regulatory sanctions, financial loss, or safety hazards. Use cases in high-stakes environments demand strict human oversight, dual verification, and conservative threshold gates.
Determine Where Human Review Is Required
Designing human-in-the-loop workflows ensures employees maintain accountability while benefiting from automated velocity.
Practical enterprise AI solutions rarely attempt 100% end-to-end autonomous execution. Instead, they implement human-in-the-loop (HITL) architecture.
Under this model, the AI performs heavy cognitive lifting: parsing unstructured text, aggregating data, scoring possibilities, and drafting outputs. The system assigns an explicit confidence score to its output. When confidence exceeds an agreed threshold (for instance, 96%), the workflow proceeds automatically. When confidence falls below the threshold, the case is routed to an experienced human reviewer with the relevant sections highlighted.
This keeps human expertise focused exactly where ambiguity and risk reside, rather than forcing skilled staff to process thousands of routine entries manually.
Consider Integration with Existing Systems
An AI model provides no business value if its outputs cannot seamlessly flow into existing operational tools and databases.
An intelligent capability cannot live on an island. If employees must leave their primary business software to open a separate web portal, copy-paste prompts, and manually re-enter results into their ERP, adoption will plummet.
During use-case evaluation, examine your existing application architecture. Does your core software expose documented REST or GraphQL APIs? Can it receive webhooks? Does your security infrastructure support role-based authentication and audit logging for automated agents?
Designing for integration from day one ensures that machine intelligence operates invisibly behind the scenes, enhancing the software tools your team already uses every day.
Define Success Metrics Before Implementation
Establish objective, quantifiable baselines before writing code so pilot performance can be measured accurately.
To determine whether an AI deployment has succeeded, organizations must document current operational baselines prior to development. Key metrics include:
• Processing cycle time: How many hours or days does the task currently take from intake to completion?
• Error rate: What percentage of manual submissions currently contain errors that require rework?
• Unit cost: What is the current operational cost per processed transaction?
• Staff capacity: What percentage of employee working hours is consumed by routine manual review?
Establishing these baselines upfront eliminates subjective debates about whether the implementation was worth the investment.
Start with a Controlled Pilot
Test the solution on a bounded, representative subset of real work before undertaking enterprise-wide rollout.
Rather than attempting an organization-wide transformation in a single release, deploy the AI capability as a controlled pilot. Limit the scope to one department, one document type, or one customer segment.
Run the pilot in shadow mode initially: let the AI generate extractions or recommendations while staff continue their normal workflow, comparing system outputs against human decisions in real time.
A controlled pilot uncovers unforeseen edge cases, data quirks, and workflow bottlenecks in a safe environment where errors carry no operational penalties.
When AI May Not Be the Right Solution
Recognizing when to decline an AI approach is just as valuable as knowing when to proceed.
Artificial intelligence is generally the wrong solution when:
1. The process requires absolute, mathematical determinism with zero tolerance for probabilistic variance.
2. Transaction volume is too low to justify the engineering, testing, and maintenance investment.
3. The business process changes so frequently that models and prompts would require weekly re-engineering.
4. Necessary training or grounding data cannot be obtained or cleaned within practical timeframes.
5. Existing software tools already offer built-in automation features that remain unused simply because staff have not been trained.
In these circumstances, standard software engineering, process optimization, or conventional automation will yield faster results with far less complexity.
SunSolv AI Use-Case Decision Checklist
Run your prospective initiative through this 10-point practical assessment before committing engineering resources:
- Is there a specific operational bottleneck that can be measured in hours, error rates, or turnaround delays?
- Have you mapped the current workflow, including inputs, handoffs, and employee decision criteria?
- Have you verified that simple rules-based automation or API integration cannot solve the problem?
- Does the task involve interpretation, pattern recognition, or unstructured data where AI has a distinct advantage?
- Do you have access to representative, legally compliant, and clean data to evaluate the solution?
- Will the measurable business return comfortably exceed upfront engineering and ongoing compute costs?
- Have you identified the cost of incorrect outputs and designed human-in-the-loop safeguards to contain risk?
- Can the solution integrate directly into your existing enterprise software via standard APIs?
- Have you defined quantitative baseline metrics (accuracy, throughput, latency) to measure pilot success?
- Is the initial project scoped as a narrow, controlled pilot rather than an all-at-once rollout?
Key Takeaway
The most successful AI initiatives do not attempt to reinvent entire enterprises overnight. They focus on concrete business friction points where probabilistic intelligence can interpret unstructured information, augment human workers, and integrate smoothly into existing operational systems. Start with the problem, respect data realities, establish clear human review boundaries, and measure outcomes against a real business baseline.