An enterprise AI pilot should be structured as a 4-to-8 week empirical evaluation bounded by pre-agreed quantitative baselines, strict budget caps, shadow-mode testing against human experts, and explicit decision gates that dictate whether to deploy, iterate, or discontinue the initiative.
SunSolv AI Pilot Lifecycle Framework
A disciplined four-phase delivery methodology for enterprise AI proof-of-concepts.
A structured execution model designed to test technical feasibility and business value within tight operational boundaries.
Baseline & Scope
"What is the exact current performance, cost, and latency benchmark?"
Measure the existing human or rules-based baseline across error rates, handling time, and throughput before introducing the pilot system.
- Do you have hard historical numbers on turnaround time and error frequencies?
- Is the pilot workflow scoped to a single discrete step rather than an entire department?
Isolated Prototype
"Does the model reliably process representative historical inputs in a sandbox?"
Build and tune the prototype against curated historical datasets in an isolated environment before connecting live feeds.
- Can the model meet accuracy benchmarks on edge cases without manual tweaking?
- Are token and compute costs logged for every inference request?
Shadow Evaluation
"How does the model perform against live data in parallel with human operators?"
Run the system in silent "shadow mode" where it evaluates real operational inputs simultaneously with human staff without acting autonomously.
- Are disagreements between human decisions and model predictions reviewed daily?
- Does latency remain within acceptable operational bounds during peak traffic?
Gate Review
"Did the initiative achieve pre-agreed quantitative hurdles to justify production?"
Hold an accountable leadership review to compare results against predefined go/no-go thresholds and make a binding investment decision.
- Did the pilot meet accuracy, speed, and unit-economic criteria?
- Is there a clear engineering plan for security, maintenance, and monitoring?
Escaping the "Pilot Purgatory" Trap
Most corporate AI experiments stall in pilot purgatory because they are treated as tech demonstrations rather than hypothesis-driven business tests with hard stop conditions.
A substantial proportion of enterprise AI proofs-of-concept stall before reaching production. Teams often spend months fine-tuning prompts, testing different model versions, and demonstrating impressive sample outputs in internal slide decks. Yet when asked whether the system is ready to handle real customer interactions or financial workflows, confidence evaporates.
This condition—commonly called pilot purgatory—is rarely caused by technological limitations. It occurs because project sponsors failed to define what "success" actually looks like before starting. Without pre-agreed quantitative targets, any output can be rationalized as interesting progress, and no result is ever conclusive enough to warrant a production release.
An effective AI pilot is not an open-ended science fair. It is an empirical business experiment designed to test a specific operational hypothesis within strict temporal and budgetary guardrails.
The Four-Stage AI Pilot Framework
A structured 4-to-8 week lifecycle ensures that AI pilots remain focused, measurable, and accountable to leadership.
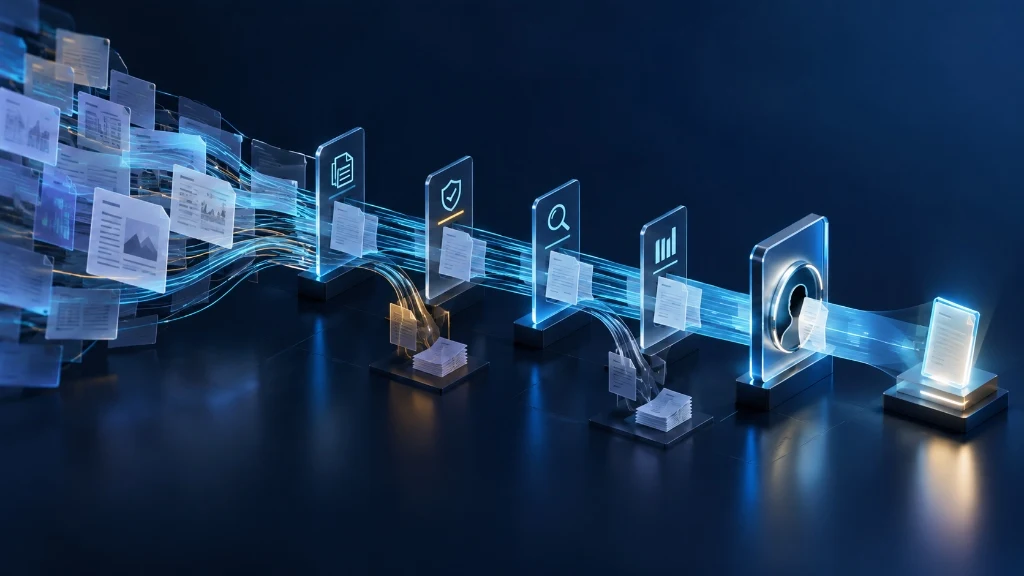
SunSolv structures enterprise AI pilots into four distinct, sequential stages: Baseline & Scope, Isolated Sandbox Prototype, Live Shadow Evaluation, and Formal Gate Review. Each phase has specific entry and exit criteria.
By dividing the pilot into these stages, leadership maintains continuous visibility over progress. If a prototype fails to achieve baseline accuracy during the sandbox phase, the initiative can be terminated or rescoped before investing in live pipeline integrations.
Establishing Quantitative Baselines First
You cannot demonstrate that an AI system improves operations unless you have measured the exact current cost, time, and error rate of the human baseline.
Before drafting a single line of pilot code, organizations must record empirical performance metrics for the existing process. If your team does not know how many minutes it currently takes a human operator to triage an inquiry, or what percentage of manual entries contain clerical errors, claiming that an AI system will "save time and reduce errors" is meaningless.
Key baseline metrics must include: average handling time per unit, 95th-percentile completion latency, baseline error and rework rates, fully loaded labor cost per transaction, and peak processing volumes.
These baseline numbers become the hurdle rate. The pilot system must demonstrate that it can either reduce unit handling time, lower operational cost, or increase capacity while keeping error rates within strictly defined safety tolerances.
Scoping a Narrow, High-Friction Operational Slice
Successful pilots target a single discrete decision point with clear boundaries rather than attempting to transform an entire end-to-end department.
A frequent error is selecting an overly ambitious pilot scope, such as "automating customer service" or "optimizing supply chain logistics." Broad scopes introduce too many variables, dependencies, and edge cases, making it impossible to isolate model performance.
Instead, select a discrete sub-task that exhibits high operational friction, repetitive structure, and measurable outputs. Examples include: categorizing incoming support tickets into one of eight routing queues, extracting line items from standardized supplier invoices, or summarizing customer call transcripts into structured CRM fields.
By constraining the scope to a single operational node, engineering teams can build robust validation, maintain clean test datasets, and complete evaluation within a 4-to-8 week window.
Before initiating prototype development, teams should also review the core AI vs automation trade-offs to ensure deterministic rules wouldn't solve the problem faster and at lower operational cost.
Shadow Testing Against Human Experts
Shadow mode testing allows you to measure model accuracy and operational latency on live production data without exposing customers or business systems to automated errors.
Never deploy an unverified AI pilot directly into a customer-facing or transaction-processing workflow. The gold standard for enterprise pilot evaluation is "shadow mode" (also known as dark launching).
In shadow mode, production transactions flow to human staff as usual. Simultaneously, a background copy of the transaction payload is sent to the pilot AI system. The AI generates its prediction, classification, or draft response and logs it into an audit datastore—without executing any external action.
At the end of each day or week, system auditors compare the AI outputs against the final decisions made by human experts. This provides an objective, side-by-side accuracy evaluation on live production traffic while keeping operational disruption and customer-facing exposure to a minimum, provided shadow data pipelines maintain strict data isolation, privacy controls, and access logging.
Hypothetical Example: 6-Week Document Triage Pilot
A structured 6-week pilot enables an objective decision on whether to proceed with production engineering.
Consider a hypothetical logistics brokerage, Meridian Freight, processing 1,200 incoming shipping rate confirmations daily via PDF email attachments. Three full-time clerks spent an average of 4.5 minutes per email manually typing shipping dates, container numbers, and quoted rates into their dispatch portal.
Meridian launched a 6-week AI pilot with three predefined success hurdles: (1) extraction accuracy of mandatory fields must exceed 95%, (2) average inference processing time must remain below 15 seconds per document, and (3) total API compute cost must not exceed $0.12 per document.
During Weeks 1–2, the team built a lightweight extraction service using document models and tested against 500 historical PDFs. During Weeks 3–5, they ran the service in shadow mode alongside human dispatchers on 3,000 live incoming emails. Discrepancies were reviewed daily.
At the Week 6 gate review, the data showed: 96.4% field extraction accuracy, 8.2-second average processing latency, and an actual unit cost of $0.07 per document. Because all three pre-agreed hurdles were met, leadership confidently authorized production integration with full human-in-the-loop exception handling.
This tiered model mirrors our recommendations for where human review belongs in AI-assisted workflows, ensuring automation accelerates delivery without bypassing vital supervisory checks.
Defining Hard Decision Gates
Every pilot must culminate in a formal gate review with only three permissible outcomes: proceed to production, pivot with new constraints, or terminate immediately.
At the conclusion of the pilot timeline, project stakeholders must convene for an accountable gate review. To prevent indefinite drifting, only three outcomes should be permitted:
- Proceed to Production: All predefined technical, operational, and financial criteria were met. Budget and engineering resources are formally allocated for security hardening, CI/CD pipeline integration, monitoring, and team training.
- Pivot: Feasibility was demonstrated, but specific addressable gaps were uncovered (e.g., higher compute costs than projected or edge-case failures in specific document types). A tightly bounded 2-week extension is approved with explicit revised targets.
- Terminate: The model failed to meet accuracy, cost, or latency thresholds, or revealed that underlying data was too inconsistent for automated handling. The initiative is shut down cleanly, findings are documented, and resources are redirected to higher-return opportunities.
Common Mistakes That Derail AI Pilots
Beware of scope creep, evaluating only on curated test sets, and failing to model ongoing operational costs.
The most destructive pilot pitfall is moving the goalposts when early results fall short. If a model was required to hit 95% accuracy to be commercially viable, but only achieves 82%, leaders must resist the urge to claim that "82% is promising" without calculating the cost of human error correction.
Another common trap is ignoring integration complexity. A pilot that runs in a standalone Jupyter notebook or isolated web form is meaningless if integrating that model with your legacy enterprise database requires an eight-month API overhaul.
Finally, teams frequently fail to model recurring inference and infrastructure expenses. An architecture that appears affordable during a 500-request pilot can become commercially unviable when scaled to 500,000 monthly transactions.
AI Pilot Readiness Checklist
Ensure these foundational criteria are locked in before development starts.
- Current baseline performance (time, cost, error frequency) is documented with empirical data.
- Success metrics are expressed in quantitative operational terms (e.g., >95% accuracy, <10s latency).
- Pilot duration is strictly capped between 4 and 8 weeks with pre-scheduled review dates.
- Total budget ceiling (including engineering hours and API compute costs) is formally locked.
- Shadow-mode evaluation architecture is prepared to test live data without operational disruption.
- Daily discrepancy review protocol is established with designated human subject-matter experts.
- Executive sponsors agree in writing to the three decision gates: proceed, pivot, or terminate.
Discipline Prevents Pilot Purgatory
An AI pilot is an empirical business experiment, not a permanent proof-of-concept. Locking in quantitative baselines, shadow-mode validation, and hard stop criteria before day one ensures your organization either scales high-return solutions or cuts losses swiftly.